AI Deployment & PerformanceIn Stock
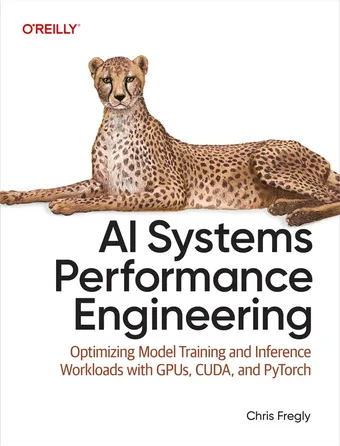
AI Systems Performance Engineering
Optimizing Model Training and Inference Workloads with GPUs, CUDA, and PyTorch
Price৳ 680
AI Systems Performance Engineering by Chris Fregly is a comprehensive guide to optimizing training and inference workloads across GPUs, CUDA, and PyTorch. Scaling modern AI architectures demands deep knowledge of hardware acceleration, kernel execution, and distributed cluster interconnects. Fregly demonstrates how to profile bottlenecks, tune CUDA and Triton kernels, and scale massive transformer models across distributed GPU topologies.
What you will learn
- Profile GPU compute and memory bottlenecks using PyTorch Profiler, Nsight Systems, and Nsight Compute
- Implement distributed training strategies with Fully Sharded Data Parallel (FSDP), Megatron-LM, and DeepSpeed ZeRO
- Accelerate model inference using vLLM, TensorRT-LLM, FlashAttention, and PagedAttention mechanisms
- Optimize memory footprints and arithmetic intensity with FP8, INT8, and INT4 quantization schemes
- Write and debug high-performance custom GPU kernels using CUDA and the OpenAI Triton language
- Configure low-latency cluster networking with NVIDIA NCCL, InfiniBand, and RoCE communication protocols
- Scale distributed batch processing and fine-tuning pipelines using Ray and PyTorch distributed runtimes
Who this is for
MLOps engineers, AI infrastructure architects, and systems developers tasked with reducing training costs and inference latency. Experience with Python, PyTorch, and basic Linux systems administration is assumed. Prior GPU kernel programming is not required.